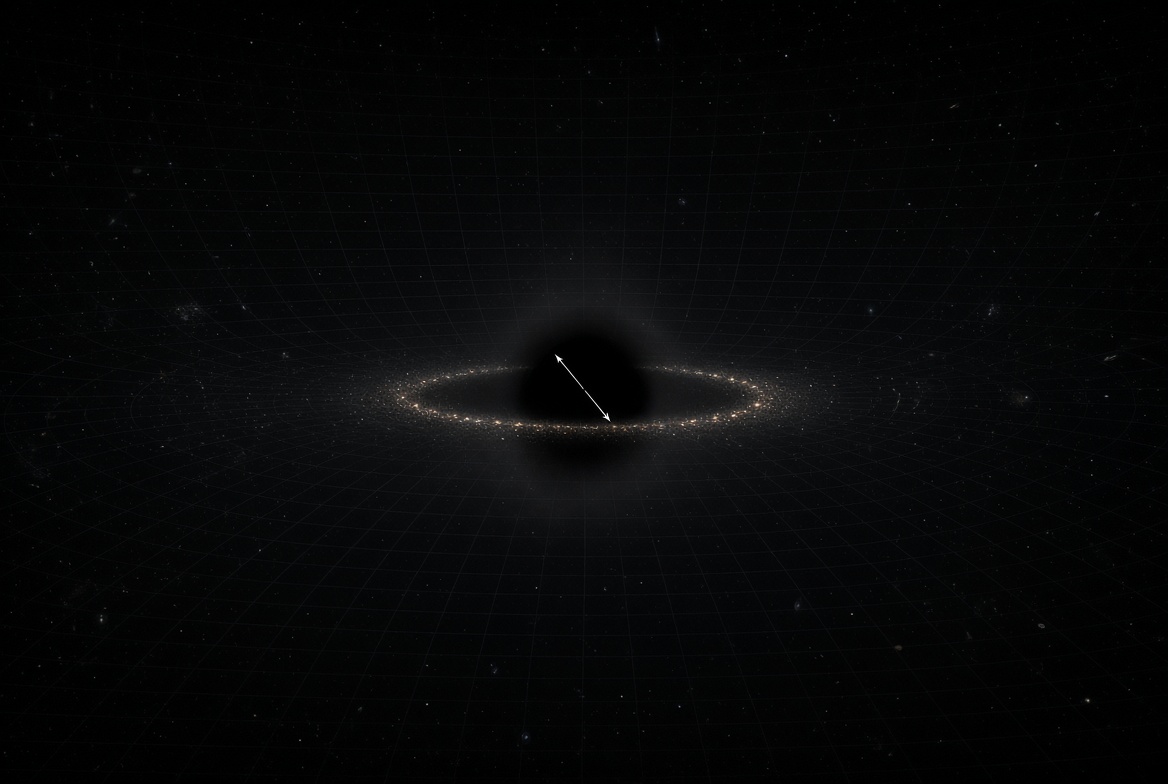
Is the universe infinite?

The question that "Is the universe infinite?" was always in my mind since I was a kid! I was baffled by thinking that there's a wall if go directly in a direction.
Read MoreBlog posts accumulated over the time.

The question that "Is the universe infinite?" was always in my mind since I was a kid! I was baffled by thinking that there's a wall if go directly in a direction.
Read MoreA hierarchy of partition functions is our knowledge of the data. With type-nn we can train it, grow it, prune it, and read it back as Ands and Ors on a graph.
Categories: Math Computer Science

Sleeping Beauty problem is an inspiration to understand the relativistic behavior of probabilities. Here, after developing a precise transformation between observers of this problem we will apply it to another known problem, the CHSH violation, and there are good news for people who are interested to understand!
Read MoreCategories: Math Probability
Tags: Mathematics Probability Relativity Bell
Update first! This is not matmul on any integer, but rather single digit matmul. I also have to mention that the code and below text was written by Grok 4.5 (Expert).
In the original MFFT post the polynomials were written down to single binary digits. The point of that choice was not aesthetics: once every coefficient is \(0\) or \(1\), a pointwise matrix product
\[ C_{ij} = \sum_k A_{ik}\,B_{kj} \]
stops being a general multiply–add. It is the count of positions where both factors are one:
\[ C_{ij} = \#{k : A_{ik}=B_{kj}=1} = \operatorname{popcount}!\bigl(\mathrm{row}_i(A)\ \mathrm{AND}\ \mathrm{col}_j(B)\bigr). \]
No scalar multiply in the leaf. Only bitwise AND and a population count along the contraction index \(k\).
mfft-bench now has that leaf on CPU and GPU. This note is the report: how we got there, what the complexity claim actually means, and the numbers on an RTX 5070 Ti.
Read MoreCategories: Math Programming FFT Matrix multiplication
A year ago I wrote about Matrix Fast Fourier Transform (MFFT): treat matrix entries as polynomials over a digit base, evaluate them at a family of matrix-valued roots of unity that are really just signed permutations, multiply pointwise, and map back. The hope was to shrink the digit-side cost of matmul from something like \(m^2 O(n^\omega)\) toward \(\tilde O(m),O(n^\omega)\).
Theory is cheap. Code is less so. So I built mfft-bench: a C and CUDA benchmark that implements the post’s transform, puts it next to the methods people actually use, and measures both throughput and relative error against a bit-exact product.
This post is the report. It worth mentioning that this post is written by Grok 4.5. Also the code was initiated by Opus 5, but concluded by Grok 4.5.
Read MoreCategories: Math Programming FFT Matrix multiplication
Search